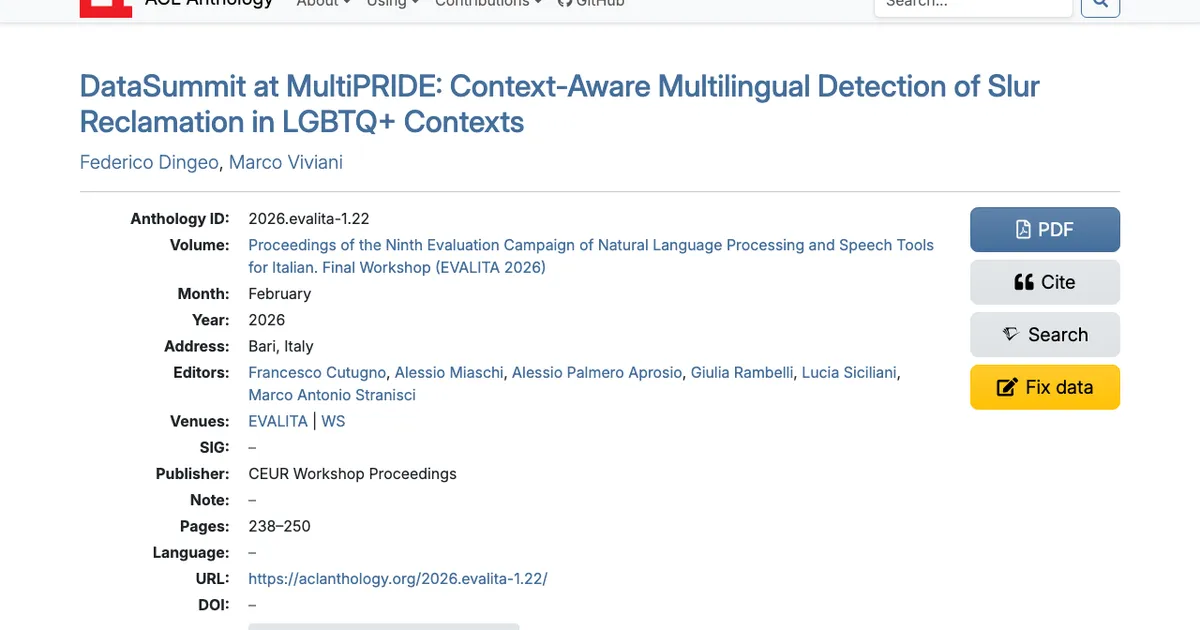
Logit-Coordinate Generative Models for Mixed Continuous-Categorical Tabular Data
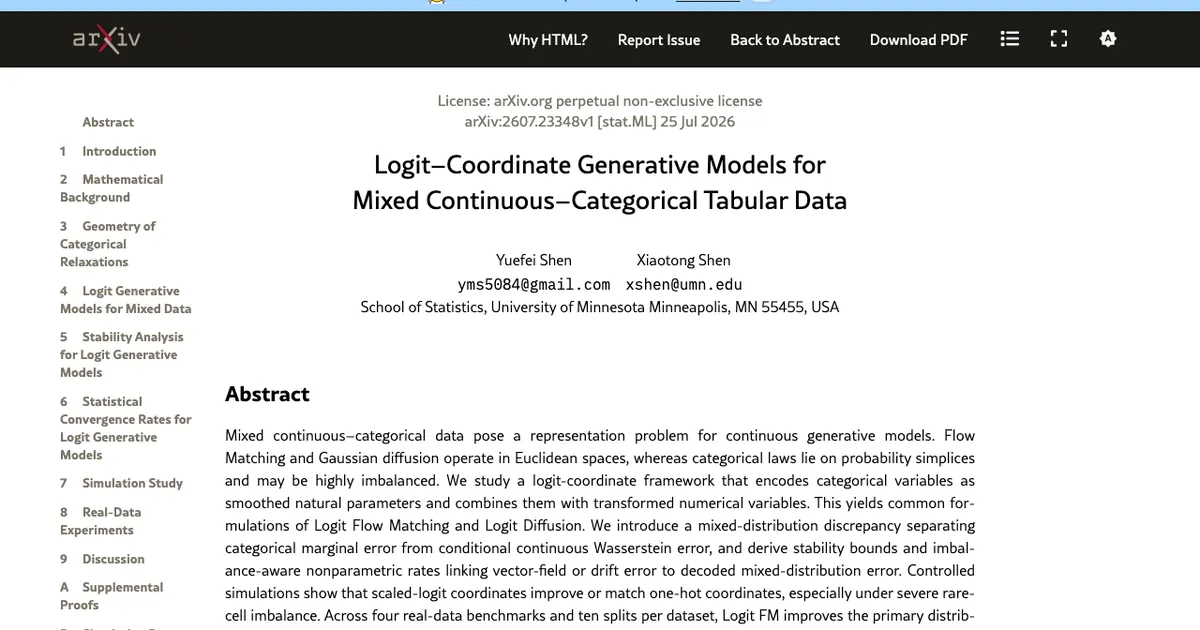
🤯 Stop Treating Categorical Data Like Numbers: A Breakthrough in Mixed ML Modeling
Ever struggled with mixed data types in machine learning? You know the pain—you have continuous features (like temperature or price) and discrete categories (like ‘Male’/’Female’ or ‘Region A’/’B’). Most powerful generative models, like Diffusion Models and Flow Matching, were built for clean, pure numbers in Euclidean space. But real-world data is messy.
This new research tackles this critical bottleneck head-on by introducing a revolutionary logit-coordinate framework.
🔬 The Core Problem: Standard continuous generative models assume all inputs are normal distributions in a smooth vector space. Categorical variables, however, follow highly discrete laws (like probability simplices) and often suffer from massive imbalances—a phenomenon called ‘rare-cell imbalance.’ Simply treating categories as one-hot encodings severely limits the model’s ability to learn complex dependencies.
🚀 What Changed? The Logit Coordinate Solution: The authors propose encoding categorical variables using their smoothed natural parameters (the logits). Instead of forcing a category into a sparse, one-hot vector, this approach transforms the discrete probabilities into a mathematically tractable, continuous coordinate system. This allows cutting-edge generative techniques—like Logit Flow Matching and Logit Diffusion—to operate effectively on mixed data.
💡 Why Does This Matter for Data Science?
- Better Generation: By resolving the mismatch between Euclidean spaces and probability simplices, these models can generate synthetic datasets (especially tabular ones) that are significantly more realistic and preserve complex statistical relationships than previous methods.
- Handling Imbalance: The logit approach is specifically shown to outperform traditional one-hot encoding, particularly when dealing with severe rare-cell imbalance—a common issue in fraud detection or medical records.
- Robustness & Theory: The paper doesn’t just propose an improvement; it provides deep mathematical guarantees, including stability bounds and imbalance-aware nonparametric rates, solidifying its theoretical foundation.
🧠 Key Takeaways for Practitioners: * If your data contains a mix of continuous measurements and categorical labels (e.g., customer behavior tracking), using the logit coordinate approach is superior to standard one-hot or simple embedding methods for generative tasks. * The results are compelling: Logit FM improves primary distributional metrics on multiple benchmarks, and Block-Conditional Logit FM consistently enhances performance on flat models.
This work represents a major step forward in the maturity of modeling complex, real-world tabular data. It’s essential reading for anyone building generative AI systems for domains like finance, healthcare, or customer analytics.
🔗 Read the full paper here: https://arxiv.org/abs/2607.23348
#GenerativeAI #MachineLearning #DataScience #TabularData #DiffusionModels #DeepLearning