Scaling Interpretable Transformers with Parity Bottleneck Layers
Decoding AI’s Brain: Meet the ParityTransformer for Interpretable LLMs 🧠✨
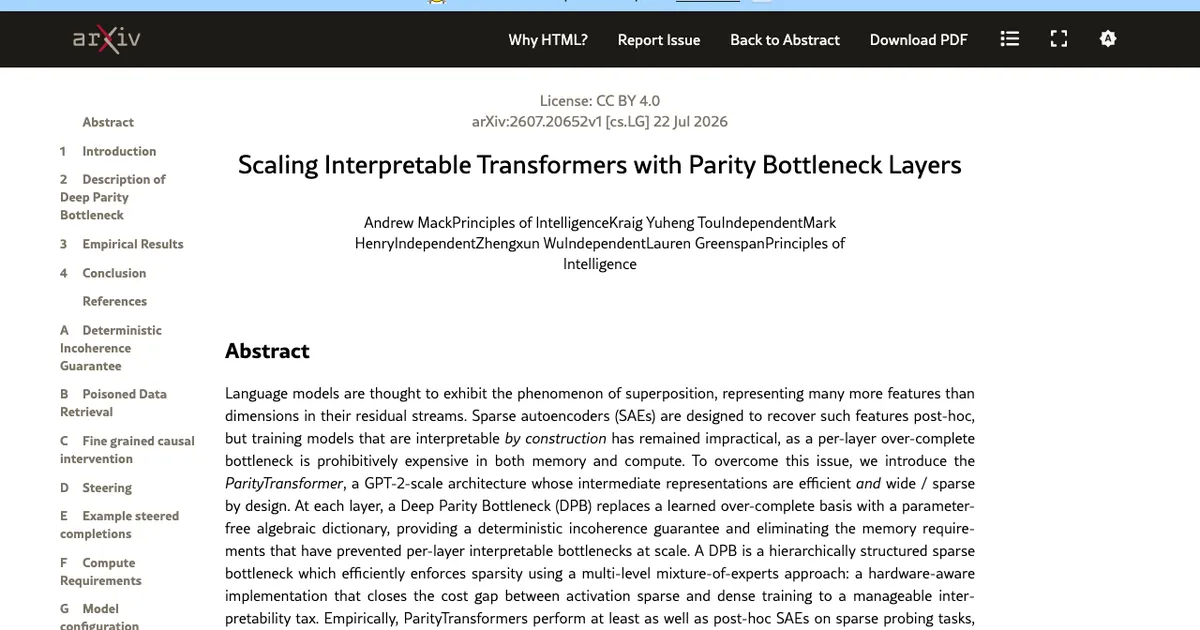
Are Large Language Models (LLMs) truly black boxes? This is the trillion-dollar question facing AI researchers, and a revolutionary new paper tackles it head-on. The abstract introduces the ParityTransformer, a novel architecture designed to solve the long-standing dilemma of making massive models genuinely interpretable by design.
🔍 Why Interpretability Matters (The ‘Why?’)
The current state-of-the-art LLMs often operate like black boxes. While they are powerful, understanding why they generate a specific output—what features or concepts they actually learned and how they combine them—is nearly impossible. We currently rely on techniques like Sparse Autoencoders (SAEs) to peek inside the model’s representations post-facto (after training). This is like looking at a photograph of a complex machine rather than observing it running.
The ParityTransformer aims to change that paradigm entirely. Instead of inferring features after the fact, this new architecture enforces an interpretable structure into its core design, making the internal workings visible from the start.
🔬 The Magic Behind Parity: How It Works
The bottleneck in creating truly interpretable LLMs has always been compute and memory. Traditional methods requiring per-layer over-complete bottlenecks are prohibitively expensive at GPT-2 scale—think massive GPU requirements just for interpretability!
The authors introduce the Deep Parity Bottleneck (DPB). This is the core innovation:
- Parameter-Free Design: The DPB replaces traditional learned bases with a simple, yet powerful, parameter-free algebraic dictionary. This deterministic structure guarantees efficient sparsity without adding memory overhead.
- Sparsity on Demand: It uses a multi-level Mixture-of-Experts (MoE) approach tailored to be hardware-aware, closing the gap between theoretical sparse training and actual deployment costs.
- Native Interpretability: Crucially, because subsequent computations only act on features that survive this efficient sparse bottleneck, the model’s features are not just ‘probed,’ but they are native products of the forward pass itself.
In simpler terms: The ParityTransformer makes sparsity a core, computationally efficient part of the model’s DNA, making its internal operations naturally traceable and manageable at scale.
🚀 Performance: Beyond Observation (The Results)
The empirical results are compelling. Not only does the ParityTransformer perform at least as well as current state-of-the-art post-hoc SAE methods on sparse probing tasks, but it also surpasses them when measuring advanced metrics like:
- Feature Absorption: How effectively concepts/features enter and influence the model.
- Steering Effectiveness: The ability to guide or control the model’s output behavior reliably.
- Causal Interventions: Manipulating specific features during inference and observing controlled changes in output—a key step toward robust AI control.
This move from ‘post-hoc interpretation’ to ‘by design interpretability’ is a fundamental leap for building trustworthy, controllable AIs.
Want to dive into the mathematics? Read the full paper on arXiv: https://arxiv.org/abs/2607.20652
This article is for educational and technical understanding; always remember that AI safety and interpretability are ongoing, crucial research areas.